Cirix
Engineered an end-to-end Retrieval-Augmented Generation platform supporting parallel ingestion of multi-format documents (PDFs, web URLs, YouTube transcripts) with source-verifiable citations.
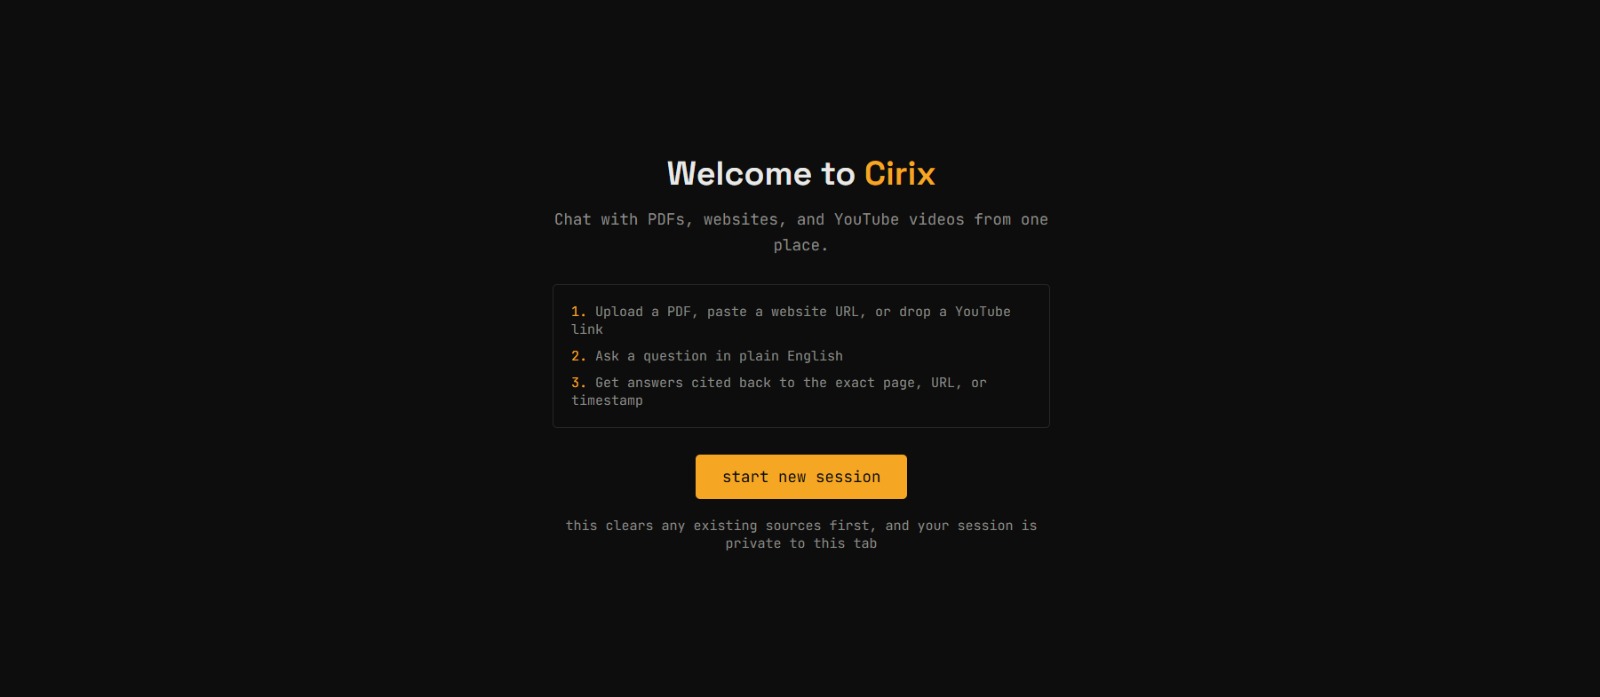
Cirix
Cirix is a Retrieval-Augmented Generation (RAG) system built on LangChain's Expression Language (LCEL). It unifies unstructured content from PDFs, web pages, and YouTube video transcripts into a single ingestion pipeline, enabling natural language querying with source citations.
Links
- Live Platform: cirix.vercel.app
- Source Code: github.com/anuptiwari17/cirix
Overview
Extracting insights across fragmented media often requires switching between dedicated tools. Cirix unifies document parsing, web scraping, and video transcript extraction into a standardized ingestion flow. Content is chunked, vector-embedded, and stored in a vector index to provide context-grounded answers with exact source page, URL, or timestamp references.
Key Features
- Unified Multi-Source Ingestion: Standardized data normalization for raw PDFs, website text, and pre-timestamped YouTube captions.
- Sentence-Aware Chunking: Recursive text splitting designed to preserve semantic sentence boundaries during vectorization.
- Context-Grounded RAG Pipeline: LangChain LCEL chain composing prompt templates, Gemini 2.5 Flash, and similarity retrievers.
- Verifiable Citations: Every generated response explicitly cites original source document pages, URLs, or video timestamps.
- Session Memory: In-memory conversation history management via
RunnableWithMessageHistoryscoped per session ID.
Tech Stack
- Frontend: Next.js 15 (App Router), TypeScript, Tailwind CSS
- Backend: FastAPI, Python, Uvicorn, Pydantic
- AI / RAG Framework: LangChain (LCEL), Gemini 2.5 Flash, Gemini Embeddings (
gemini-embedding-001) - Vector Database: ChromaDB (
langchain-chroma) - Document Processing: PyMuPDF (
fitz), Trafilatura,youtube-transcript-api - Hosting: Vercel (Frontend), Render (Backend API)